Mistaken identity ties a person to a stranger’s bad press when search engines associate similar names, details, or entities and surface unrelated negative content for the wrong individual. Reputation management is the structured process of understanding, monitoring, and managing information that shapes how a person or entity is perceived online.
What is mistaken identity in online reputation?
Mistaken identity in online reputation is the incorrect association between an individual and information belonging to another person with a similar identity. Within search ecosystems, identity association depends on signals such as names, locations, occupations, photographs, usernames, organisations, and linked references. When these signals overlap, content indexing can connect separate entities within search results even when the underlying people are unrelated.
The problem is fundamentally an entity perception issue. Search engines organise information around entities and relationships rather than interpreting every page as an isolated document. A negative article, review, forum post, or public record can therefore become associated with the wrong entity when contextual signals create sufficient similarity. The resulting search visibility does not necessarily represent the actual history or behaviour of the person being searched.
Mistaken identity also affects online credibility because users frequently interpret search results as evidence about the person represented by a query. A person encountering negative content attached to a similar name can form an inaccurate perception before examining the underlying details. Reputation signals therefore depend not only on what information exists online but also on whether search systems and users correctly attribute that information.
How do search engines connect the wrong person to negative content?
Search engines connect people to content through relationships between identity signals, page information, and indexed references. A name alone provides limited entity differentiation, so algorithms evaluate additional contextual information to understand which person a page concerns. When those contextual signals are incomplete or ambiguous, content belonging to one individual can become visible for searches associated with another.
A search engine analyses signals including textual references, structured information, links, location data, professional details, and references across websites. These signals contribute to SERP evaluation, which determines the relevance and ordering of indexed pages for a particular query. If a negative page contains a name matching the searched individual and lacks sufficient distinguishing information, the page can enter the same search environment.
This does not mean that a search engine has established factual responsibility. Ranking primarily concerns relevance and retrieval rather than independently verifying every identity claim contained on a webpage. The distinction is important because search visibility represents what an algorithm retrieves for a query, while factual identity represents who actually performed an action or was involved in an event.
Why does a similar name create reputation risk?
A similar name creates reputation risk because names function as important but imperfect identity identifiers within digital information systems. Two unrelated individuals can share identical names, initials, surnames, or common spelling variations. Search systems then require additional signals to distinguish their respective entities.
Identity separation becomes more difficult when both people operate in similar professional or geographic contexts. For example, identical names combined with overlapping locations, industries, employers, or social profiles create a denser network of potentially related information. Search engines evaluate these relationships as part of content retrieval, while users often make rapid judgements based on visible search results.
The digital footprint of each individual also influences separation. A well-defined digital footprint contains consistent information that establishes professional identity, location, organisational relationships, and other distinguishing attributes. An incomplete footprint provides fewer signals for differentiating one entity from another, increasing ambiguity within search results.
How does negative content influence search perception?
Negative content influences search perception through its visibility, relevance, prominence, and contextual association with an identified entity. A search results page presents a selection of indexed documents rather than a complete representation of every fact about a person. The position and wording of those documents influence which reputation signals receive attention first.
Content ranking dynamics determine which pages appear prominently for searches involving a person’s name. Search engines assess factors such as relevance, authority, content quality, links, freshness, and query relationships when ordering results. A negative page with strong relevance and authority can therefore receive substantial visibility even when its subject is a different individual with a similar identity.
Search perception is distinct from factual reputation. Online reputation refers to the collective information and signals that shape perceptions of an individual or entity across digital environments. When incorrect information becomes visible for a person’s name, the search perception associated with that name can diverge from the person’s actual record.
What role does content indexing play in mistaken identity?
Content indexing determines whether information becomes available to search systems and therefore forms a fundamental layer of mistaken-identity problems. Indexing is the process through which search engines discover, analyse, and store information from webpages and other accessible sources. Once indexed, content becomes eligible to participate in search retrieval when its signals correspond with a user’s query.
The indexed representation of a page includes information extracted from its text, metadata, links, entities, and surrounding context. Search systems use these signals to understand what the page concerns and which queries it relates to. If the page identifies a person ambiguously, the indexed representation can retain that ambiguity.
Indexing therefore does not equal verification. A page entering a search index does not establish that every identity association expressed or implied by the page is accurate. Understanding this distinction helps explain why incorrect search associations persist: retrieval systems organise available information according to identifiable signals rather than functioning as universal identity-verification databases.
How do reviews affect mistaken-identity reputation signals?
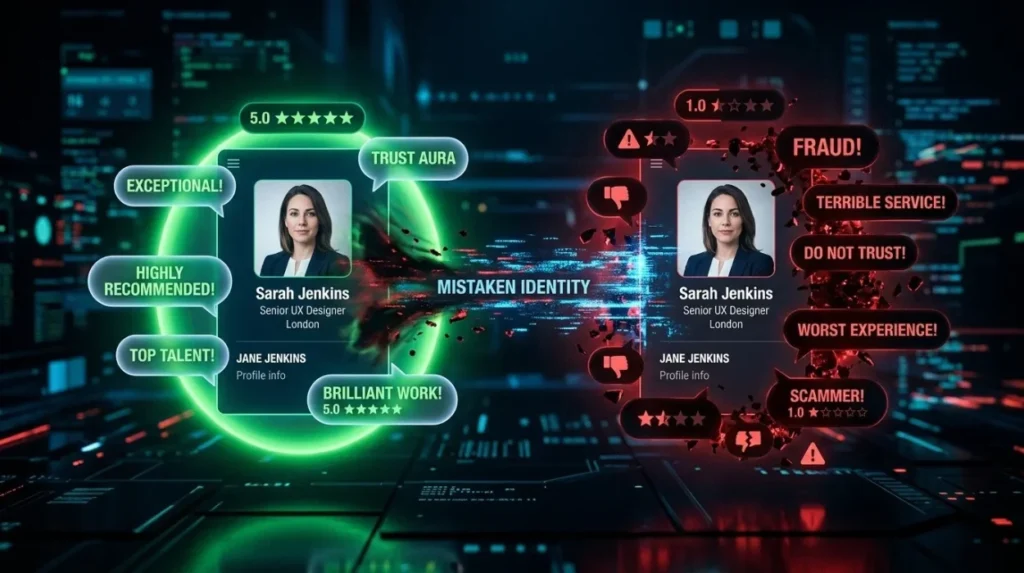
Reviews affect mistaken-identity reputation signals by adding sentiment, behavioural descriptions, ratings, and entity references to the searchable information environment. Review platforms frequently connect feedback to names, profiles, businesses, locations, or professional identities. When two entities share identifying attributes, review information can contribute to incorrect associations.
Sentiment interpretation adds another layer because search systems and users can identify positive or negative language within reviews. A negative review attached to the wrong entity can therefore introduce unfavourable reputation signals into searches involving a similar name. The effect becomes more significant when review content is indexed, highly visible, or repeated across interconnected platforms.
Review signals also differ from verified identity evidence. A rating or written comment represents information published by a reviewer, while search algorithms determine how that information is retrieved and displayed. Understanding this distinction prevents the assumption that a prominent negative review automatically establishes that the person named in a search result is responsible for the underlying conduct.
Why do authority and trust signals matter in identity confusion?
Authority and trust signals matter because search engines use signals about sources and content to determine relevance and reliability within their ranking systems. Authoritative websites, established publications, recognised organisations, and strongly connected pages can receive substantial visibility. When incorrectly attributed information appears on such a source, its search prominence can increase.
Authority is not equivalent to identity accuracy. A highly authoritative publication can contain information about one person while a searcher incorrectly interprets that information as referring to another person with the same name. The authority of the source affects visibility, while identity attribution depends on the contextual signals connecting the content to a particular entity.
Trust signals operate across the wider information environment. Consistent professional profiles, authoritative references, organisational affiliations, and accurate biographical information create additional context for entity differentiation. These signals help search systems interpret relationships between pages, people, organisations, and topics rather than relying exclusively on a single matching name.
How does mistaken identity affect a person’s digital footprint?
Mistaken identity affects a digital footprint by introducing information that does not accurately belong to the individual being searched. A digital footprint is the collection of publicly accessible information associated with a person across websites, platforms, databases, publications, and other online environments. When unrelated content becomes connected to that footprint, the visible identity profile becomes internally inconsistent.
Inconsistency affects entity perception because search engines and users encounter conflicting information about the same apparent person. A professional profile can describe one occupation while a negative article references a different individual with the same name. Without sufficient contextual separation, both documents can enter the same search landscape.
The resulting problem is not simply the existence of negative content. It is the relationship between identity attribution, content indexing, search visibility, and user interpretation. Analysing these components separately provides a clearer understanding of why mistaken identity produces reputation risk.
How can identity signals be distinguished in search results?
Identity signals can be distinguished by examining the contextual attributes that separate one entity from another. Search analysis focuses on the relationship between names, locations, occupations, organisations, photographs, profiles, dates, and other identifying information. These attributes provide a framework for evaluating whether two pieces of content actually refer to the same person.
A structured identity analysis typically evaluates:
- Compare identifying attributes — Match names against location, occupation, employer, education, photographs, and other available identifiers to determine whether the content refers to the same entity.
- Analyse source context — Examine the wording, author, publication, dates, and surrounding references to establish which individual the content identifies.
- Evaluate search relationships — Review how pages appear for name-based queries and whether unrelated documents repeatedly enter the same SERP environment.
- Separate factual attribution — Distinguish confirmed identity information from assumptions created by similar names or incomplete contextual signals.
This process treats mistaken identity as an information-architecture problem rather than simply a negative-content problem. The central question is whether the available reputation signals correctly represent the intended entity.
What happens when mistaken-identity content remains highly visible?
When mistaken-identity content remains highly visible, the incorrect association continues to participate in search perception. Repeated exposure gives the content greater prominence within the search environment, particularly when it appears for exact-name or closely related identity queries. Users can encounter the negative information before finding pages that establish the correct identity.
Persistent visibility also creates an information imbalance. The search results may contain accurate information about the individual alongside unrelated negative information about another person. Without clear entity separation, users must perform additional evaluation to determine which information actually applies.
This demonstrates why reputation analysis requires more than counting positive and negative pages. The relevant variables include search visibility, source authority, entity relationships, content relevance, sentiment signals, and identity accuracy. Evaluating these variables reveals whether a reputation issue originates from genuine information about the person or from incorrect attribution.
Dive Deeper With Our Expert Guides:
Why Your Teenage Posts Can Sabotage Your Adult Life
How Landlords Research Tenants’ Online Reputations
How is mistaken identity different from genuine negative reputation content?
Mistaken identity concerns incorrect attribution, whereas genuine negative reputation content concerns information that actually relates to the individual being searched. The distinction depends on identity evidence rather than the positive or negative tone of the content. A negative page about the correct person represents a different reputation condition from a negative page concerning someone with a similar identity.
The distinction can be evaluated through source context, dates, locations, professional records, photographs, organisational affiliations, and other identifying information. Consistency across these signals increases confidence that content relates to the intended entity. Contradictions between the content and the individual’s established identity indicate an attribution issue requiring further analysis.
This distinction also changes how search visibility is interpreted. A prominent result is not automatically an accurate result, and a negative result is not automatically a legitimate reputation signal for the searched person. Entity perception depends on whether the information retrieved by the search engine corresponds to the correct individual.
Why does accurate entity perception matter for online credibility?
Accurate entity perception matters because online credibility depends on whether available information forms a coherent and attributable representation of an individual. Searchers use professional profiles, publications, reviews, organisational references, and other sources to understand an entity’s identity. Incorrect associations introduce contradictory signals into that evaluation process.
Online credibility therefore involves both information quality and information attribution. A credible search environment contains signals that accurately identify the person, establish relevant context, and connect information to the correct entity. When attribution fails, unrelated information can distort the perceived digital footprint.
Understanding these mechanisms also explains why Correcting Mistaken-Identity Content That’s Hurting You belongs within a broader reputation framework. Identity correction focuses on the relationship between content and entity, while search perception analysis examines how that relationship affects visibility and interpretation across SERPs.
What are the key principles of mistaken-identity reputation analysis?
Mistaken-identity reputation analysis centres on accurate entity identification, contextual attribution, and search-system interpretation. The issue exists at the intersection of information retrieval and digital identity rather than solely within the content itself. A reliable analysis therefore separates the source of information, the identity represented by that source, and the way search systems connect the information to a query.
The key principles are:
- Identify the entity — Establish the distinguishing attributes that separate the searched person from individuals with similar identities.
- Analyse attribution — Determine which person the original content actually describes using contextual evidence.
- Evaluate indexing — Establish how the content enters search systems and which identity queries retrieve it.
- Assess visibility — Examine ranking position, source authority, relevance, and recurrence within SERPs.
- Separate perception from fact — Distinguish search-engine retrieval from verified evidence about the individual’s actual history.
These principles demonstrate that mistaken identity is fundamentally a problem of information association. Search visibility, reputation signals, authority, sentiment, and content indexing interact to determine how an entity is represented online.
How does mistaken identity shape online reputation?
Mistaken identity shapes online reputation when search systems associate a person’s identity with content that actually belongs to someone else. Reputation management is therefore partly an exercise in understanding how digital information is indexed, connected, ranked, and interpreted. Names, contextual identifiers, reviews, authority signals, and digital footprints collectively influence entity perception within search ecosystems.
The central distinction is between what content says, who that content concerns, and how search engines retrieve it. When those three elements become misaligned, negative information can influence search perception without accurately representing the individual. Analysing identity signals and content relationships provides the factual basis for understanding such reputation discrepancies.
How does mistaken identity affect your online reputation?
Mistaken identity can connect your name with negative articles, reviews, or public records belonging to another person. This can affect search visibility and create inaccurate reputation signals when users encounter unrelated content in search results.
Why does Google show someone else’s bad press when I search my name?
Search engines use identity signals such as names, locations, occupations, organisations, and linked references to match content with search queries. When people share similar identifying details, unrelated negative content can appear for the wrong person’s name.
Can someone else’s negative reviews damage my online reputation?
Yes, unrelated reviews can influence online perception when they are incorrectly associated with your identity in search results or online profiles. Review signals such as ratings, sentiment, and repeated references can affect how your digital footprint is interpreted.
How can I tell if negative search results are about someone else?
Compare the content’s identifying details with your own information, including location, occupation, employer, photographs, dates, and professional affiliations. Consistent differences across these signals can indicate that the negative content concerns another individual with a similar identity.
Can Clear My Name help with mistaken identity online?
Clear My Name provides reputation management for individuals, including analysis of online information associated with a person’s identity. Mistaken-identity issues require examining content attribution, search visibility, and the identity signals connecting information to the wrong person.