Correcting mistaken-identity content requires separating inaccurate identity associations from legitimate information and then evaluating whether removal, suppression, or content enhancement addresses the underlying search problem. Reputation management strategies differ based on the source, accuracy, authority, and search visibility of the content affecting an individual’s digital identity.
What makes mistaken-identity content different from ordinary negative content?
Mistaken-identity content is different because the central problem is inaccurate attribution rather than simply negative sentiment. Online reputation control methods are evaluated through the relationship between the published content, the person it describes, and the entity represented in search results. A negative article about the correct individual represents a reputation issue, while an article about a stranger with the same name represents an identity-association issue.
This distinction changes the appropriate analytical framework. Content accuracy, identity evidence, source context, and search ranking influence need to be assessed before selecting an intervention. Removing or suppressing content without establishing the attribution problem can address visibility while leaving the underlying identity confusion unresolved.
The search environment also introduces a separate layer of interpretation. Search engines retrieve and rank information according to relevance and available signals rather than independently determining whether every identity association is factually correct. Consequently, a high-ranking result can create an inaccurate perception even when the underlying page concerns another person.
How does content removal compare with content suppression?
Content removal addresses the source itself, while content suppression focuses on reducing the prominence of unwanted information within search results. Removal operates by seeking an appropriate mechanism for taking content offline, correcting an inaccurate record, or changing access to the source. Suppression operates by strengthening other relevant search results so that unwanted pages receive less prominence for targeted queries.
Removal provides a direct intervention when the content has a legitimate correction or removal pathway. Its limitation is that control over the source generally rests with the publisher, platform, website owner, or applicable legal and policy framework. A successful source-level change also does not automatically eliminate copies, cached material, references, or separate pages discussing the same information.
Suppression works at the search-visibility level rather than necessarily changing the original source. It can influence SERP composition by increasing the relative prominence of relevant, authoritative information. Its limitation is that the underlying page remains available and can continue generating reputation signals if users locate it through alternative queries or direct navigation.
Is removal more effective than suppression for mistaken identity?
Effectiveness depends on whether the identity error can be addressed at its original source. Removal directly changes the availability or presentation of the disputed content, whereas suppression changes its relative position within the search environment. The two approaches therefore measure different outcomes rather than representing interchangeable versions of the same intervention.
When a publisher has clear evidence that content concerns another individual, source-level correction creates a stronger connection between factual identity and online information. The intervention targets attribution rather than only visibility. Where source-level correction is unavailable, search-focused methods address the separate problem of how the incorrect association appears within SERPs.
A useful evaluation separates content correction from search visibility control. Correction concerns whether the information accurately identifies the person, while suppression concerns how prominently that information appears. Treating these as separate variables provides a clearer measurement of reputation signals and entity credibility.
How does content creation compare with content removal?
Content creation builds additional identity signals, while content removal attempts to reduce or eliminate a specific source of unwanted information. Content creation operates through the development of accurate, authoritative, and relevant digital assets that provide search engines with additional context about an individual. Removal operates by addressing the original content through an available editorial, platform, contractual, or legal mechanism.
Content enhancement can improve entity differentiation when new material contains consistent professional identifiers and authoritative references. Stronger contextual information gives search systems additional material for interpreting which pages belong to the intended entity. However, creating content does not automatically correct an inaccurate third-party attribution.
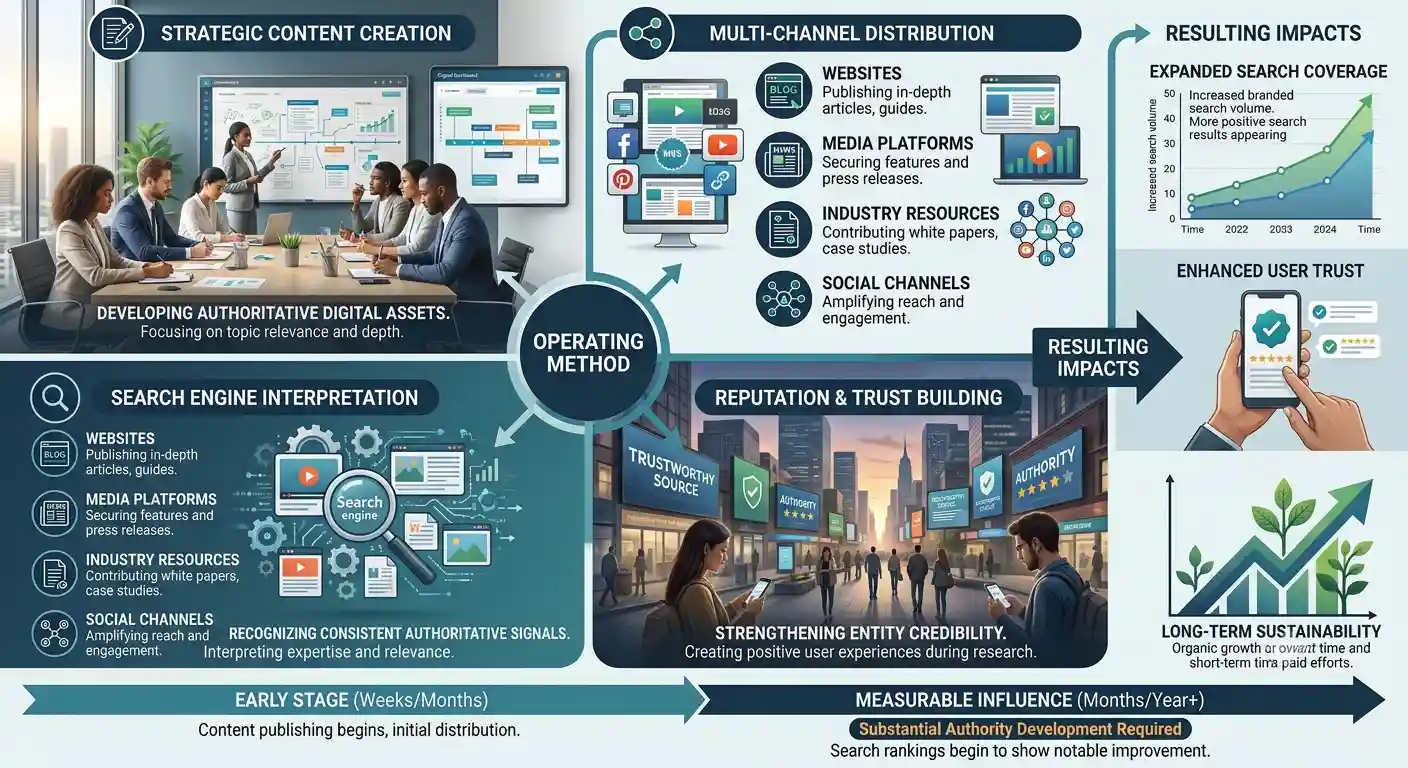
Removal offers a more direct relationship with the problematic source when a valid removal mechanism exists. Its limitation is dependency on external control, because the publisher or platform determines whether the source changes. Content creation therefore offers greater control over the material being produced, while removal offers greater directness when the source itself is eligible for correction.
What is the difference between organic and reactive reputation strategies?
Organic reputation strategies build a consistent digital identity before or independently of a specific reputation incident, while reactive strategies respond to an identified search or content problem. Organic activity operates by developing authoritative information, maintaining accurate profiles, and establishing consistent entity signals over time. Reactive activity operates by addressing a particular negative result, inaccurate association, review, article, or indexed page.
The organic approach supports long-term entity credibility because search systems receive a stable pattern of identity information. Consistent professional details across reputable sources create relationships that help differentiate an individual from people with similar names. The limitation is that organic development does not directly address a specific harmful page that already has strong search visibility.
Reactive intervention provides greater topical precision because it targets an identified source or search-result problem. It can therefore respond directly to a mistaken identity association affecting a name query. Its limitation is that isolated interventions do not necessarily create the broader identity structure required for sustainable search perception.
Which approach provides stronger short-term search visibility control?
Reactive intervention provides more immediate control over a defined search problem because it begins with an identified result, source, or identity association. The process focuses resources on the specific content affecting the SERP rather than waiting for a broader digital footprint to develop. Short-term measurement therefore centres on changes in visibility, ranking position, indexing, and attribution.
Removal can produce a direct visibility change when the source is successfully altered or removed from search-accessible environments. Suppression can produce a different short-term effect by changing the composition and ordering of results around a target query. Content enhancement generally operates through the gradual accumulation of stronger signals and therefore has a different time horizon.
Short-term visibility does not establish long-term resolution. A suppressed page can remain accessible, a removed page can have duplicates, and newly created content can lose prominence as search systems recalculate relevance. Measuring short-term impact therefore requires separate tracking of source status and SERP composition.
How does long-term reputation sustainability differ between approaches?
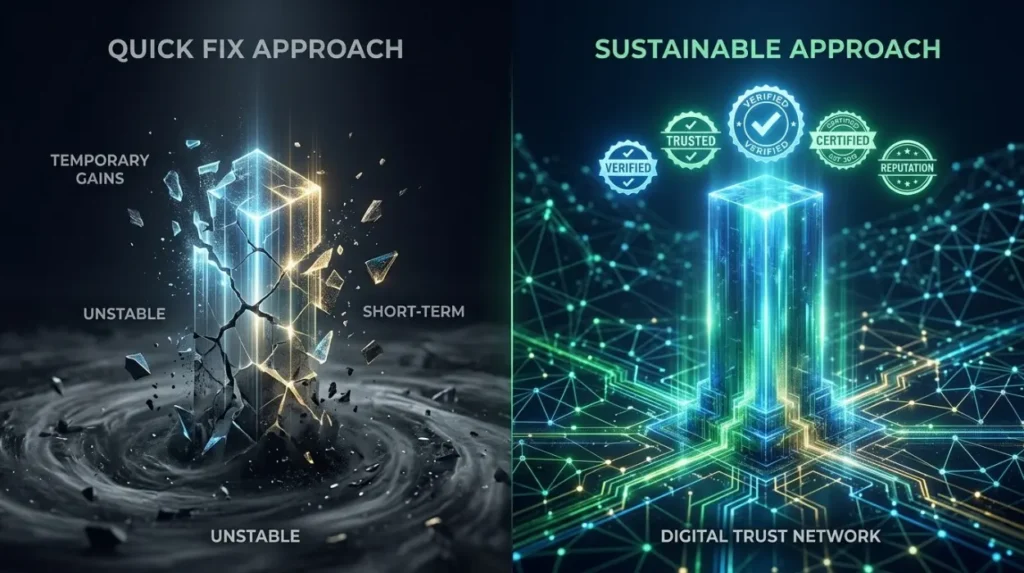
Long-term sustainability depends on whether an approach addresses the underlying identity structure as well as the immediate search result. Organic content enhancement establishes persistent information about the intended entity, while source-level correction addresses inaccurate information at its origin. Suppression focuses on maintaining a favourable SERP composition without necessarily changing the source itself.
Sustainable reputation control therefore involves understanding how signals interact over time. Consistent information across authoritative sources strengthens entity credibility and provides additional context for future searches. In contrast, a strategy focused exclusively on one ranking position has a narrower scope because search results change as new information is indexed.
Sustainability also depends on recurrence. A mistaken identity problem involving a common name can reappear when new pages use the same ambiguous identifier. Maintaining accurate entity signals reduces the information gap that permits unrelated content to enter the same search environment.
How should content suppression and content enhancement be evaluated?
Content suppression and content enhancement are evaluated through different indicators because they influence SERP composition through different mechanisms. Suppression is measured through changes in the visibility and ranking of targeted negative results, while enhancement is measured through the prominence and relevance of accurate identity information. Both approaches require monitoring rather than relying on a single search observation.
A practical evaluation framework can be structured as follows:
- Measure source visibility — Record the position, indexing status, and query variations associated with the mistaken-identity content before assessing change.
- Analyse entity signals — Compare names, locations, occupations, organisations, dates, and other identifiers across the disputed source and accurate profiles.
- Evaluate SERP composition — Track which authoritative pages occupy prominent positions and whether unrelated content continues appearing for identity-based queries.
- Assess sentiment distribution — Examine how positive, neutral, and negative content is distributed across visible search results rather than counting pages alone.
- Monitor recurrence — Check whether new indexed pages recreate the same identity association through repeated names or contextual similarities.
This framework distinguishes visibility outcomes from factual correction. A ranking change demonstrates an alteration in search exposure, while a source correction demonstrates an alteration in the underlying information. Both measurements contribute to understanding whether the reputation system is becoming more accurate.
Dive Deeper With Our Expert Guides:
Auditing and Cleaning Up Your Teenage Digital Footprint
Building a Tenant-Ready Online Reputation Before Renting
How do search engines interpret reputation signals from different sources?
Search engines interpret reputation signals through combinations of relevance, authority, context, links, structured information, and other ranking factors. No single signal universally determines how an individual appears in search results. Instead, search ranking influence emerges from the interaction between indexed information and the query being evaluated.
Authoritative sources can have strong visibility because their content possesses signals associated with established information quality and relevance. Reviews contribute different signals because they contain sentiment, ratings, user-generated descriptions, and platform-specific context. Professional profiles provide identity attributes that help establish entity relationships.
This means that reputation analysis cannot treat every webpage as an equivalent unit. A highly authoritative publication, a professional directory, a social profile, and a forum comment occupy different positions within the information ecosystem. Evaluating their relative visibility, contextual relevance, and identity accuracy provides a more precise assessment of search perception.
What role does entity credibility play in correcting identity confusion?
Entity credibility is the strength and consistency of signals establishing that online information relates to a specific individual. It operates through identifiable relationships between professional profiles, authoritative publications, organisations, social accounts, directories, and other sources. Strong entity credibility gives search systems additional contextual evidence for distinguishing people who share similar names.
For mistaken identity, this distinction is particularly important because the problem involves competing identity signals. A stranger’s negative content can introduce one set of signals, while accurate professional information introduces another. The search ecosystem evaluates the available relationships when determining which content satisfies a person’s name-based query.
Improving entity credibility therefore differs from simply adding positive content. The objective is not an arbitrary increase in favourable pages but the development of coherent, attributable information. Consistency, authority, relevance, and identity specificity determine whether new material contributes meaningful reputation signals.
How do short-term and long-term strategies work together?
Short-term and long-term strategies operate at different levels of the same reputation system. Short-term interventions address immediate search visibility, source-level problems, or inaccurate associations, while long-term activity establishes a durable information structure around the correct entity. Combining the two approaches creates separate mechanisms for immediate control and ongoing identity clarification.
The distinction becomes important when mistaken-identity content has strong search ranking influence. A short-term response can address the visible SERP problem while longer-term content enhancement strengthens the surrounding identity signals. Without the longer-term component, recurring ambiguity can continue to generate similar search associations.
The reverse also has limitations. Building a strong digital footprint without addressing an established inaccurate result leaves the original association intact. Strategic evaluation therefore considers both the current SERP composition and the future stability of the entity’s online representation.
How can risk exposure be compared across reputation management methods?
Risk exposure varies according to the degree of control, dependency, and persistence associated with each method. Removal depends on the policies and decisions of the content owner or platform, while suppression depends on changes within search rankings. Content enhancement depends on the quality, relevance, authority, and continued indexing of newly developed information.
Removal carries a source-dependency risk because an intervention can fail when no legitimate correction pathway exists. Suppression carries persistence risk because the underlying content remains available and search algorithms continuously reassess rankings. Content enhancement carries maintenance risk because new information requires ongoing accuracy and relevance to remain useful within the search ecosystem.
A balanced evaluation therefore examines control as well as outcome. The relevant question is not simply which method changes a result fastest, but which mechanism addresses the specific source of risk with an appropriate level of sustainability and exposure.
How should mistaken-identity correction strategies be selected?
Strategy selection depends on the relationship between content accuracy, source control, search visibility, and identity ambiguity. When the content is demonstrably about another person, attribution evidence becomes central to the evaluation. When the source cannot be changed, search visibility and entity clarification become separate strategic considerations.
A structured decision process compares:
- Assess attribution — Establish whether the content actually identifies the intended individual using verifiable contextual signals.
- Evaluate source control — Determine whether the publisher or platform provides a legitimate mechanism for correction, amendment, or removal.
- Measure search exposure — Analyse ranking position, query coverage, indexing status, and recurrence across relevant SERPs.
- Compare intervention scope — Match removal, suppression, and content enhancement to the specific layer where the problem exists.
- Review sustainability — Measure whether the intervention continues to distinguish the correct entity as search results and indexed content change.
This approach prevents content removal, suppression, and enhancement from being treated as universally interchangeable. Each method operates on a different component of the reputation system and therefore requires different effectiveness and risk measurements.
Which factors determine the right mistaken-identity strategy?
Correcting mistaken-identity content requires evaluating both the underlying attribution problem and its effect on search visibility. Removal targets the source, suppression targets SERP prominence, and content enhancement strengthens accurate identity signals. Organic approaches establish long-term context, while reactive approaches address defined search problems with greater topical specificity. Fix Mistaken-Identity Search Results With Clear My Name provides a focused approach to addressing incorrect identity associations in search results.
The central evaluation involves content accuracy, entity credibility, search ranking influence, source authority, sentiment distribution, risk exposure, and sustainability. A strategy becomes analytically appropriate when its mechanism corresponds to the layer creating the reputation problem. Understanding these differences allows mistaken-identity content to be assessed as an information and search-system issue rather than as a simple question of positive versus negative results.
How can I correct mistaken-identity content online?
Start by documenting the incorrect information and showing evidence that the person named or described is someone else. Depending on the website, correction may involve contacting the publisher, requesting an amendment, or pursuing a content removal process.
Can mistaken-identity content be removed from Google search results?
Google does not generally remove webpages simply because information is inaccurate, so the original source often needs to be corrected or removed first. Once the source changes, search results can update as Google recrawls the page.
What evidence can prove an online identity mistake?
Useful evidence can include accurate professional profiles, company records, official documents, publication dates, and other reliable information that distinguishes two people with similar names. The strongest evidence directly connects the incorrect claim to the wrong individual and establishes the correct identity.
How long does it take to fix incorrect identity information online?
The timeframe depends on whether the publisher accepts corrections, whether the content qualifies for removal, and how quickly search engines recrawl updated pages. A correction can therefore take from a short period to several weeks or longer.
Can Clear My Name help with mistaken-identity reputation problems?
Clear My Name can help assess mistaken-identity content, identify the source of the inaccurate association, and determine whether correction, removal, or search-result suppression is appropriate. The suitable approach depends on the content, publisher policies, available evidence, and search visibility of the incorrect information.