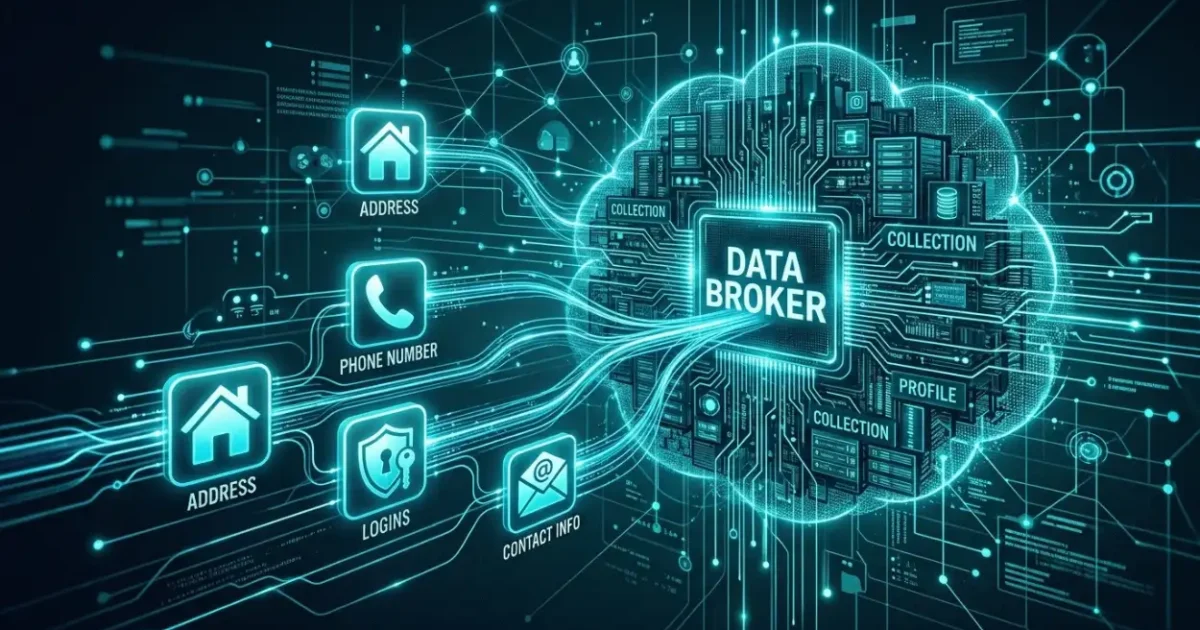
People-search sites publish addresses and phone numbers by aggregating information from public records, commercial databases, data brokers and other accessible sources. These sites organise the collected data into searchable profiles, making personal information visible through their own pages and sometimes through search engine results.
Reputation management is the structured process of understanding, monitoring and influencing information that affects how an individual or entity is represented online. Online reputation refers to the collection of information, opinions, references and reputation signals that shape perceived credibility across digital platforms and search ecosystems. People-search listings form part of this digital footprint because personal information can become indexed, ranked and associated with an identifiable individual.
Why do people-search sites publish personal information?
People-search sites publish personal information because their business models depend on collecting, organising and presenting data about identifiable individuals. The information generally comes from sources that already contain names, addresses, telephone numbers or other identifying attributes. Data aggregation systems combine these records into profiles that make separate pieces of information easier to search.
How does data aggregation create a people-search profile?
Data aggregation refers to the process of collecting information from multiple databases and linking records that appear to describe the same person. Matching systems use attributes such as names, previous addresses, telephone numbers, age ranges and associated individuals to connect records. The resulting profile presents information in a consolidated format rather than requiring a user to examine each underlying source separately.
This aggregation process changes the accessibility of personal information. An address appearing in a public record has a different search footprint from the same address appearing within a dedicated people-search profile. The people-search page creates an additional indexed location where the information can be discovered, evaluated and associated with an individual entity.
Where do people-search sites obtain addresses and phone numbers?
People-search sites obtain addresses and telephone numbers through data sources that contain publicly available, commercially licensed or otherwise accessible information. These sources include public records, property-related records, directory information, marketing databases and data broker datasets. Aggregation platforms combine these sources to construct searchable identity profiles.
How do public records contribute to personal data?
Public records contain information created through government, legal, property or administrative processes. Depending on the record type and applicable rules, an individual’s name can become associated with an address or other identifying information. Data aggregation systems extract relevant fields and incorporate them into broader identity datasets.
How do commercial databases expand the digital footprint?
Commercial databases provide another layer of information used in identity matching and profile construction. Organisations collect data for legitimate commercial purposes such as marketing, verification, directory services or analytics. Data brokers can then licence or distribute elements of those datasets, allowing information to move between separate digital systems.
The result is a broader digital footprint. Digital footprint refers to the collection of information associated with an individual across interconnected online and offline data systems. People-search listings represent one component of this footprint because they transform underlying records into a searchable identity representation.
How do people-search sites connect an address or phone number to an individual?
People-search sites connect personal identifiers through identity-resolution systems that compare data attributes and determine whether separate records represent the same entity. Names alone provide limited certainty because identical names can belong to different people. Matching systems therefore examine combinations of addresses, telephone numbers, relatives, age ranges and historical records.
What role does entity matching play?
Entity matching is the process of determining whether different records refer to the same real-world individual. A system evaluates overlapping attributes and creates relationships between records with sufficient similarity. These relationships allow a people-search platform to construct a profile that contains current and historical information.
Entity perception extends beyond the data field itself. Search ecosystems interpret connected information as signals describing an identifiable entity, particularly when the same name repeatedly appears alongside consistent locations, organisations or references. Accuracy therefore depends on the quality and consistency of the underlying records.
Why can an old address remain associated with someone online?
An old address can remain associated with an individual because historical records are retained within databases and can continue circulating between data sources. Updating one database does not automatically update every independent dataset containing the same information. Replication creates persistence across the broader digital footprint.
How does data replication affect personal information?
Data replication occurs when information is copied, licensed, redistributed or incorporated into another database. A historical address can therefore survive after an individual has moved because the original record remains available within an independent dataset. New databases can also acquire the historical information before or after an existing listing changes.
This creates a distinction between data correction and data propagation. Correcting an entry at one source addresses that particular record, while propagated copies remain subject to their own database processes. Search visibility can therefore continue even after information changes at its original source.
How does personal information appear in Google search results?
Personal information appears in Google search results when a people-search page containing that information is discovered, indexed and considered relevant to a search query. Search engines analyse the page’s content, structure, authority and relationship to the query before determining its position within the SERP. Indexing therefore creates a pathway between a people-search database and public search visibility.
What determines whether a people-search page ranks?
Ranking depends on multiple search-system signals rather than the presence of an address or telephone number alone. Search engines evaluate relevance, content quality, page accessibility, site-level authority and relationships between entities and queries. A people-search page can therefore become visible when its information closely matches a name-based search.
SERP evaluation also considers how competing pages satisfy the same query. If professional profiles, social pages, directories, news articles or other authoritative resources contain stronger entity signals, the people-search result competes against those sources for visibility. Search ranking is therefore a comparative process rather than a simple reflection of the information’s existence.
How do people-search listings affect online reputation?
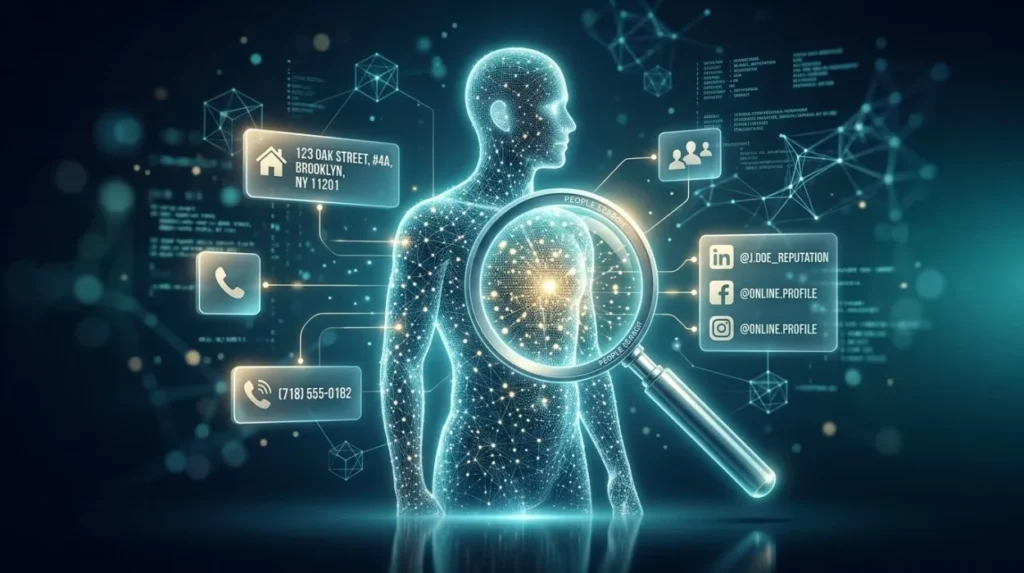
People-search listings affect online reputation by introducing personal information into the collection of indexed signals associated with an individual. Reputation refers to the perception formed from available information rather than a single webpage or database entry. A people-search result can therefore contribute to the overall digital context surrounding an individual’s name.
How does content influence entity perception?
Content influences entity perception by providing information that search systems and users associate with an identifiable entity. An address, telephone number or historical location represents a factual attribute, while surrounding pages provide additional context about the person. The combination of these signals contributes to how an entity is represented across search results.
Online credibility is also influenced by consistency between sources. When professional, social, directory and informational pages present coherent information, search systems have stronger contextual evidence for entity identification. Inconsistent or outdated records introduce additional complexity into SERP interpretation and entity matching.
How do reviews and sentiment affect reputation signals?
Reviews and sentiment affect reputation signals by providing evaluative information about an entity rather than simply factual identifiers. Review content contains opinions, ratings, recurring themes and sentiment indicators that search systems can associate with businesses, organisations or public-facing individuals. These signals differ from people-search data because they describe perceived experience or quality rather than identity attributes.
How is sentiment interpreted within search ecosystems?
Sentiment analysis examines linguistic patterns and evaluative expressions within content to identify positive, negative or neutral attitudes. Search systems use a broad range of contextual signals when understanding pages and entities, while users also interpret sentiment directly from visible search results. Repeated themes across independent sources can therefore influence perception even when individual statements vary.
Reviews are particularly relevant to reputation because they combine content with structured signals such as ratings. A rating provides a numerical representation, while written commentary supplies contextual information. Together, these elements form a distinct reputation layer within an entity’s broader search presence.
How do authority and trust signals influence personal search results?
Authority and trust signals influence personal search results by helping search systems evaluate the reliability, relevance and contextual value of available content. Authority relates to the strength and recognition of a source within a particular information environment, while trust concerns the reliability and quality of the information presented. These concepts contribute to how pages compete for search visibility.
Why does source authority matter?
Source authority matters because search engines need to distinguish between pages that provide useful information and pages with weaker contextual relevance. Established publications, recognised organisations and authoritative websites can carry stronger contextual signals than low-quality or poorly connected pages. This does not guarantee a particular ranking position, but it affects the competitive environment within SERPs.
Trust signals also operate through consistency. When multiple credible sources independently identify an entity using compatible information, the search ecosystem receives stronger evidence about that entity’s identity and context. The resulting information network contributes to SERP evaluation.
Dive Deeper With Our Expert Guides:
How a Viral Embarrassing Moment Becomes Your First Search Result
Why University Admissions Now Check Applicants’ Social Media
Why does removing personal details require understanding the source?
Removing personal details requires understanding the source because different copies of the same information exist within separate data systems. A search result is not necessarily the original source of the information, and a people-search page can itself represent only one layer of a wider data network. Identifying the underlying source establishes which part of the information ecosystem contains the relevant record.
How does source identification affect information control?
Source identification separates primary records from aggregated or replicated versions. A primary record contains the information at its original or authoritative location, while an aggregated record reproduces information obtained elsewhere. These distinctions affect the mechanisms available for addressing inaccurate, outdated or unwanted information.
The broader process of Removing Your Personal Details From People-Search Websites therefore involves understanding how personal information moves between databases, how profiles are constructed and how search engines index the resulting pages. The technical structure of the information network determines where visibility originates and how changes propagate across connected systems.
What happens after personal information is indexed?
After personal information is indexed, it becomes available to search systems as part of the searchable web corpus. Indexing does not guarantee permanent ranking, but it creates the technical condition for a page to appear in response to relevant queries. Continued visibility depends on whether the page remains accessible, relevant and competitive within the search ecosystem.
How can search visibility change over time?
Search visibility changes as search engines recrawl pages, update indexes and reassess ranking signals. Competing content also changes, creating a continuously evolving SERP environment. A people-search result can therefore move in response to changes in its own page, the wider website, competing documents or the search engine’s evaluation systems.
This distinction explains why online reputation is dynamic rather than fixed. Digital information can be created, duplicated, updated, de-indexed, replaced or re-ranked over time. Reputation analysis therefore examines relationships between information sources, entity signals, content indexing and search visibility rather than treating one search result as a complete representation of an individual.
How does the digital footprint shape online credibility?
The digital footprint shapes online credibility by providing the information environment through which an individual or entity is evaluated. It includes factual records, professional information, social references, reviews, directory entries and other indexed content. Each source contributes a different type of signal to the wider search ecosystem.
A strong understanding of digital footprint structure distinguishes factual identity information from evaluative reputation content. Addresses and telephone numbers primarily identify an entity, while reviews and professional references provide contextual or evaluative information. Search engines process these different content types within a connected information environment, while users interpret the combined results when assessing online credibility.
Why do people-search sites publish your address and phone number?
People-search sites publish addresses and telephone numbers because they aggregate information from public records, commercial datasets, directories and other data sources into searchable identity profiles. The resulting profiles can become part of an individual’s digital footprint and gain search visibility when search engines index and rank the associated pages.
Understanding this process requires examining data aggregation, entity matching, content indexing, SERP evaluation and reputation signals together. Personal information exists within a wider network of records rather than in isolation, which explains why historical data can persist and why search visibility can continue across independent sources. Online reputation is therefore shaped by the interaction between information availability, source authority, entity perception and search-system evaluation.
Why do people-search websites have my address and phone number?
People-search websites collect and aggregate information from public records, directories, data brokers and other accessible databases. The information is combined into searchable profiles that associate addresses and phone numbers with identifiable individuals.
How do people-search sites get your personal information?
People-search sites obtain personal information through sources such as public records, commercial databases, property records and directory listings. Data aggregation systems then match these records using names, addresses, telephone numbers and other identifying attributes.
Can a people-search website publish an old address?
Yes, an old address can remain listed because historical records are retained and replicated across independent databases. Updating one source does not automatically remove the same information from other data broker or people-search databases.
How does personal information on people-search sites affect online reputation?
People-search listings contribute to an individual’s digital footprint and can become visible in search engine results. Their presence adds another source of information that users and search systems can associate with an individual’s online identity and credibility.
Can you remove your personal details from people-search websites?
Removal depends on the website’s policies, the source of the information and the available privacy or opt-out process. Clear My Name addresses this type of issue through personal information removal services, which focus on reducing the public availability of personal details across relevant sources.